
Joining a pile of small text files into one readable document
How the Text File Merger decides what goes first, what it puts in the joins, what the CSV switch really does to your header rows, and a step by step run on twelve monthly exports with the counters you should see afterwards.
Why anybody ends up with fifty text files
Very little software writes one long file. Programs that keep a log start a fresh one every night. Accounting systems hand you one export per month. A chat history arrives split into days. Notes apps save one file per note. None of that is a problem until the day you want to search across the lot, or hand the whole thing to somebody as a single attachment.
At that point you need the contents joined, in a sensible order, with some way of telling later where each chunk came from. That is the entire job of this page.
- Daily server logs you want to grep through in one pass.
- Monthly sales exports that belong in one spreadsheet.
- Chapter drafts written as separate documents.
- A pile of meeting notes going into an archive.
- Subtitle or transcript pieces that were split for translation.
Order by: five ways to line them up
The first menu decides the sequence, and it matters more than people expect. Get it wrong and the merge is a shuffle rather than a joining.
File name is plain alphabetical. That is fine for dates written the sensible way round, such as 2024-03-07, because those sort correctly as text. It is wrong for anything counted. Alphabetically, export-10 lands between export-1 and export-2, because the ten is read letter by letter.
File name, numbers in order fixes exactly that. It reads any run of digits as a number, so 2 comes before 10 and part9 comes before part11.
Date modified puts the oldest first, which is what you want for logs that carry no useful name. Size puts the smallest first, which is rarely the sequence you want but is handy for spotting the empty ones. The order I added them keeps whatever sequence your browser handed over when you dropped the files in.
Between files: what sits in the joins
The second menu chooses what marks the boundary between one file and the next, and each choice produces something you can predict exactly.
A heading with the file name writes a line made of five equals signs, the file name, and five more equals signs. Because it names the source, it is the only choice that lets you work backwards later from a line in the merged text to the file it came from. It also appears above the very first file, not only between pairs.
A line of dashes writes a run of sixty hyphens on its own line. It reads well and takes up almost no room, but it does not tell you which file you have just moved into. A blank line simply leaves an empty row. Nothing at all puts the files straight up against each other, which is what you want when the result has to be read by a program rather than a person.
The three switches
Beside the two menus sit three tick boxes. None of them is on by chance, and one of them changes your data rather than its layout.
- Treat as CSV, keep only the first header row: the top line of the first file is kept, and the top line of every file after it is thrown away. It also compares those top lines, and if a later one is not identical you get a warning naming the files.
- Trim blank lines at the ends: removes an empty first line and all the empty space at the bottom of each file, so the joins stay tight instead of collecting gaps.
- Number the files: adds a running count to the file name in the heading, so the first join reads 1. notes-march.txt. This only shows up when Between files is set to the heading, because the number lives in the heading and nowhere else.
- A Clear button on the same row empties the whole list, and every row of the file table has its own Remove button if you only want to drop one.
Twelve monthly exports, joined properly
You have twelve files called export-1.csv through export-12.csv. Each starts with the same header line: date,region,units,total. Each has a few hundred rows under it.
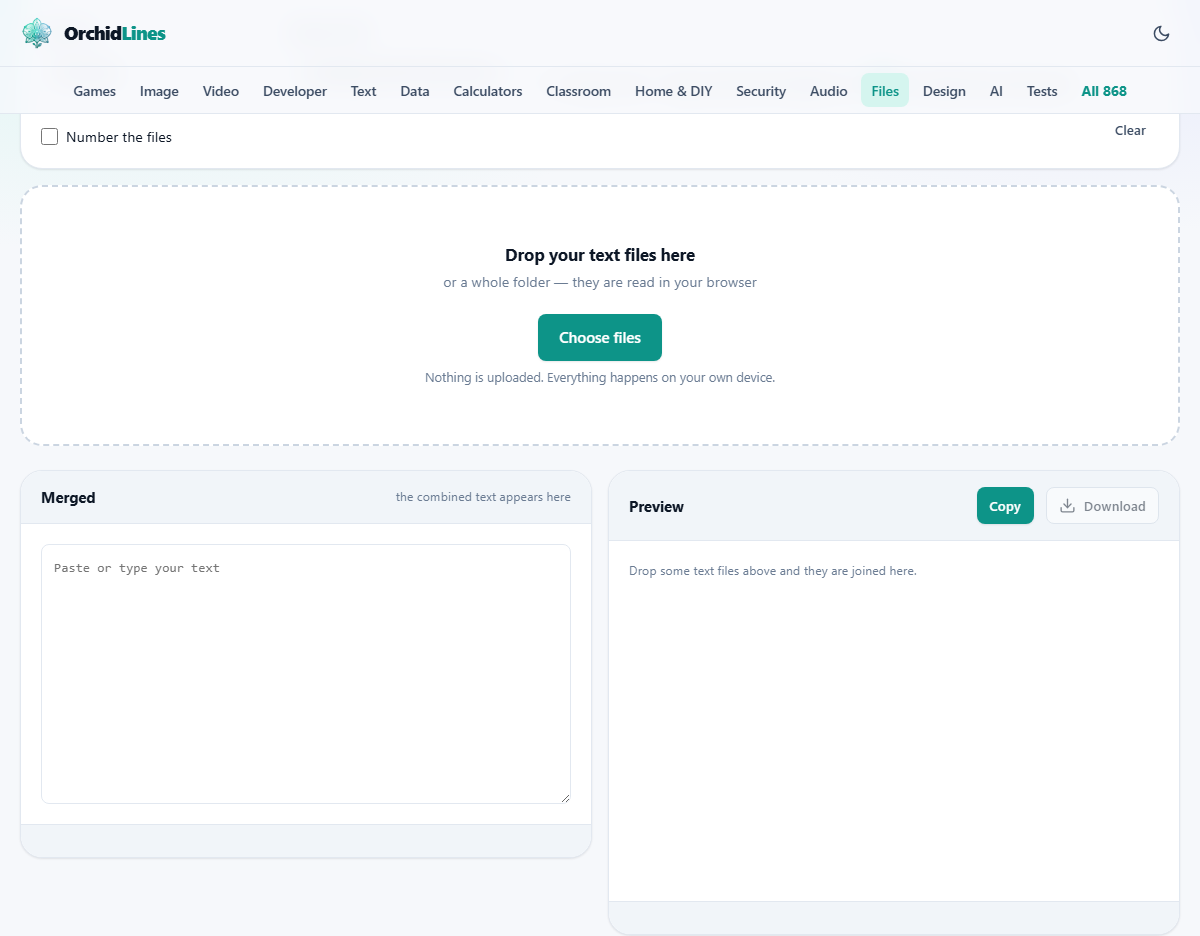
Drop them all in. A table appears listing each file with its size and the date it was last changed. Set Order by to File name, numbers in order, or the year will run January, October, November, December, February. Set Between files to Nothing at all, because a spreadsheet does not want decoration in the middle of its data. Tick Treat as CSV. Leave Trim blank lines at the ends ticked.
The right hand pane fills with the joined text. Above it sit four counters: files merged 12, lines, characters, and skipped, which should read none. The result begins with a single date,region,units,total line and then runs straight through every row of every month.
Now suppose a warning appears in orange naming export-9.csv. That means somebody added a column halfway through the year. The tool still removed the top line of that file, so its rows are in your merged data with their columns shifted one place. Open that file, fix its columns, and merge again before the numbers reach anyone.
The same folder as a readable log
Change nothing except the two menus and you get a completely different document. Set Between files to A heading with the file name and tick Number the files.
The result now opens with a line reading five equals signs, then 1. export-1.csv, then five more, followed by that month's rows. Then a blank gap, then the second heading, and so on. Nothing was lost and nothing was combined differently. The only change is that a human can now scroll through it and always know where they are.
Reading the counters and the preview
The four counters under the preview are worth a glance every time. Files merged is the number that actually made it in, and if it is lower than the number of rows in your table, something was left out. Lines and characters describe the finished text.
Skipped is the one that catches problems. Anything with a lot of control bytes near the start is treated as not being text at all and is left out, with its name listed there. A stray picture or a compressed archive caught up in the selection lands here. It is deliberate, because pasting the raw bytes of a picture into the middle of a document corrupts the whole thing.
The preview itself shows the first twenty thousand characters and then says there is more. That is only a display limit. What you copy or download is the whole thing.
Getting the text out
There are two buttons in the head of the preview panel. Copy puts the entire merged text on your clipboard, ready to paste into an editor. Download beside it writes it to a file.
That file is always called merged.txt. If you merged spreadsheet exports, rename it to end in .csv before you open it, otherwise the spreadsheet will treat it as plain text and put everything in the first column. The contents are correct either way, it is only the ending that decides which program takes it and how.
Where merges quietly go wrong
- You merged the same file twice. Dropping a second batch adds to the list rather than replacing it. Check the table, or press Clear and start again.
- The header trick was left off. Without the CSV switch, twelve exports give you twelve header rows scattered through the data, and eleven of them look like ordinary records.
- The order looks random. Plain alphabetical order was chosen for numbered files. Switch to the option that reads numbers as numbers.
- A file came out empty. Look at the skipped counter first; a file saved in an unusual encoding can read as control bytes.
- Odd characters at a join. Some programs put an invisible marker at the very start of a file. That marker is stripped here, so if you still see stray symbols they were in the original text rather than added by the merge.
When this is not the tool you want
This joins text, one file after another, and that is all it does. It has no idea what your columns mean. If two exports have the same rows and you want them matched up side by side rather than stacked, a spreadsheet is the right place for that work.
It also does not touch names. If the problem is that your files are called a mess and you want them tidied instead of combined, the bulk renamer handles that side of things. And if the files are documents rather than plain text, joining their raw contents will not give you a readable document; export each one to text first, then come back.
Read on your device, joined on your device
Your files are opened by the browser you are sitting in front of. The text is put together in that browser's memory, the preview is drawn from the same memory, and the download is written by your own machine. At no point does any part of a file travel over your connection.
This matters more than usual here, because the things people merge tend to be logs, records and exports, which are exactly the files that carry names, addresses and figures nobody else should see.