
Splitting a large CSV into smaller files by rows or by column value
Some import systems have a row limit. Some jobs are easier when each region, customer, or month sits in its own file. This article covers both ways to split a CSV -- by a fixed number of rows per file and by the distinct values in a column -- and explains the controls, the preview, the header behaviour, and the ZIP download so that every piece arrives ready to open.
When splitting is the right move
The most common reason is an import limit. Many CRM and email-marketing platforms cap uploads at a few thousand rows. A file of twenty thousand contacts must be broken into pieces that each fit under the cap. Splitting by row count solves that problem in seconds.
The second reason is organisational. A sales team wants one file per territory. A finance department wants one file per month. An operations team wants to send each warehouse its own subset. Splitting by the values in a column produces exactly that: a separate file named after each value, with only the rows that match.
A third, less obvious reason is performance. A spreadsheet that takes thirty seconds to open because it has two hundred thousand rows is painful to work with. Splitting it into ten files of twenty thousand rows each makes every file snappy, and you only open the one you need.
Loading the file
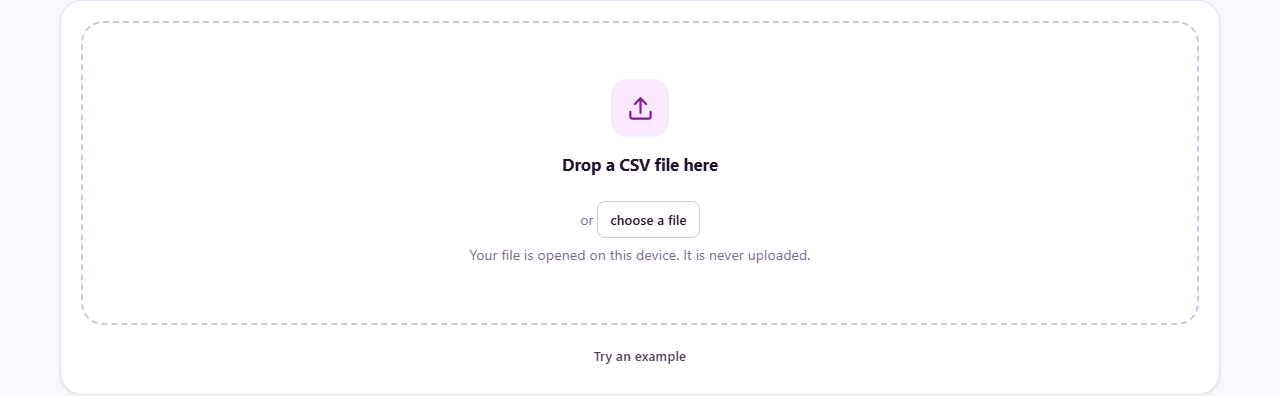
The page opens with a drop zone. You can drag a CSV file onto it, or click the choose a file button inside it to open a file picker. The accepted formats include .csv, .tsv, and plain text files. A Try an example button below the drop zone loads a sample file so you can explore the controls without using your own data.
Once a file is loaded, the row and column counts appear in a short info line. The controls panel becomes visible, showing the splitting options. If the file is large, loading takes a moment but everything happens locally. The file is read by your browser and is never sent to a server.
Splitting by row count
The Split dropdown starts on into files of so many rows. Below it, the Rows per file field defaults to 1,000. Change that number to whatever your target system requires. If your import limit is 5,000 rows, set it to 5,000. If you want four equal pieces from a file of 20,000 rows, set it to 5,000.
The preview that appears below the controls lists every file that will be produced, with the number of rows in each. The last file may hold fewer rows than the others if the total is not evenly divisible. This preview lets you confirm the split before downloading, so there are no surprises.
Splitting by column value
Change the Split dropdown to into one file per value in a column and a second dropdown labeled Column appears, populated with the column names from your file. Pick the column you want to split on. The preview updates to show one entry per distinct value, with the row count for each.
File names are built from the values themselves. A region column with values North, South, East, and West produces files called North.csv, South.csv, East.csv, and West.csv. If a value contains characters that are not allowed in file names, such as slashes or colons, those characters are replaced with hyphens so the download always works.
If the column has hundreds of distinct values, the tool warns you. Splitting a file into three hundred pieces is usually a mistake, and the warning gives you a chance to reconsider before creating an unmanageable pile of tiny files.
The header row and the Excel mark
The checkbox labeled First row is the column names, repeat it in every file is on by default. When it is on, the first row of your original file is treated as a header and copied to the top of every output file. Each piece can then be opened or imported on its own without needing a separate column-name document.
This means the total row counts across all output files add up to slightly more than the original, by one row per file. That is expected. If the person who receives one piece counts the rows, they will see the header plus their data rows, matching the number shown in the preview.
The second checkbox, Make Excel read accents correctly, adds a UTF-8 byte-order mark at the start of each file. Without it, Excel on Windows tends to read accented characters as nonsense. Leave it on unless the receiving system objects to the mark. Most modern systems either expect it or ignore it harmlessly.
Downloading the results
The Split and download button assembles the output files and triggers the download. If the split produces a single file, it downloads on its own as a plain CSV. If there are two or more files, they arrive together as a ZIP archive. The ZIP is assembled in the browser, so no upload or server processing is involved.
An estimate line next to the button gives you a rough idea of the download size before you press it. For very large files the assembly may take a few seconds, during which a progress indicator keeps you informed.
A worked example with a customer list
Suppose you have a CSV of 18,400 customer records with columns Name, Email, Country, and Signup Date. Your email platform accepts at most 5,000 rows per upload. Set the Split dropdown to into files of so many rows and type 5000 in the Rows per file field. The preview shows four files: three with 5,000 rows and one with 3,400.
Now imagine you instead want one file per country. Change the dropdown to into one file per value in a column and pick Country. The preview shows one entry per country: United Kingdom with 7,200 rows, United States with 6,100, India with 3,800, and Australia with 1,300. Each file is named after the country and contains only the matching records, with the header repeated at the top.
In both cases you press Split and download, and a ZIP file arrives. You unzip it and have the files ready to upload or send onward.
Files without a header row
Not every CSV has a header. Some machine-generated exports start straight with data. In that case, untick the First row is the column names checkbox. The first row is treated as a data row, and no header is copied into the output files. The column dropdown for splitting by value shows generic names like Column 1, Column 2, and so on.
If you leave the box ticked on a file with no header, the first data row becomes the header and is repeated in every piece but missing from the data. That is a quiet error and worth checking: if the preview shows one fewer row than you expected, your first row was eaten as a header.
Mistakes to watch for
The biggest mistake is splitting by a column that has too many distinct values. Splitting by a unique-ID column gives you one file per row, which is never useful. The warning catches this, but it is worth thinking about before you start.
Another error is setting the row count too low. If the import limit is 5,000 and you set the split to 100, you produce two hundred files when four would have been enough. More files means more uploads and more chances for someone to miss one or import one twice.
Delimiter confusion is another trap. If the file uses semicolons and the tool reads it with commas, every output file will contain one enormous column because the split ran against data that was never properly parsed. If the preview shows a single column with commas visible inside the values, the delimiter is wrong. The profiler or the repair tool can help you figure out the correct one before you split.
Also be aware that splitting does not filter. If your file has rows you want to exclude, remove them before splitting. A column-value split includes every distinct value it finds, including blanks and misspellings, so cleaning the data first saves you from producing a file called blank.csv alongside your real output.
Privacy and local processing
Your file is read by your browser and stays on your device. It is never uploaded anywhere. The split files and the ZIP archive are assembled locally and downloaded directly to your machine. You can verify this by disconnecting from the internet after the page has loaded: the entire process still works.